
Applications

Auto Added by WPeMatico

Nous Research Ships Bot Mode for Hermes Agent, Turning Agent Profiles Into a Roster of Named Bots

Nous Research has shipped Bot Mode for Hermes Agent, its MIT-licensed open source agent. Bot Mode replaces the single-agent session list with a roster of named bots. Each bot is a real Hermes profile, with its own chat, memory, skills, and pinned model. Bots message each other through a persistent Agent Inbox and hand work […]
Nous Research Ships Bot Mode for Hermes Agent, Turning Agent Profiles Into a Roster of Named Bots Read More »

ByteDance Seed and Tsinghua AIR Introduces CUDA Agent: A Large-Scale Agentic RL System for CUDA Kernel Generation

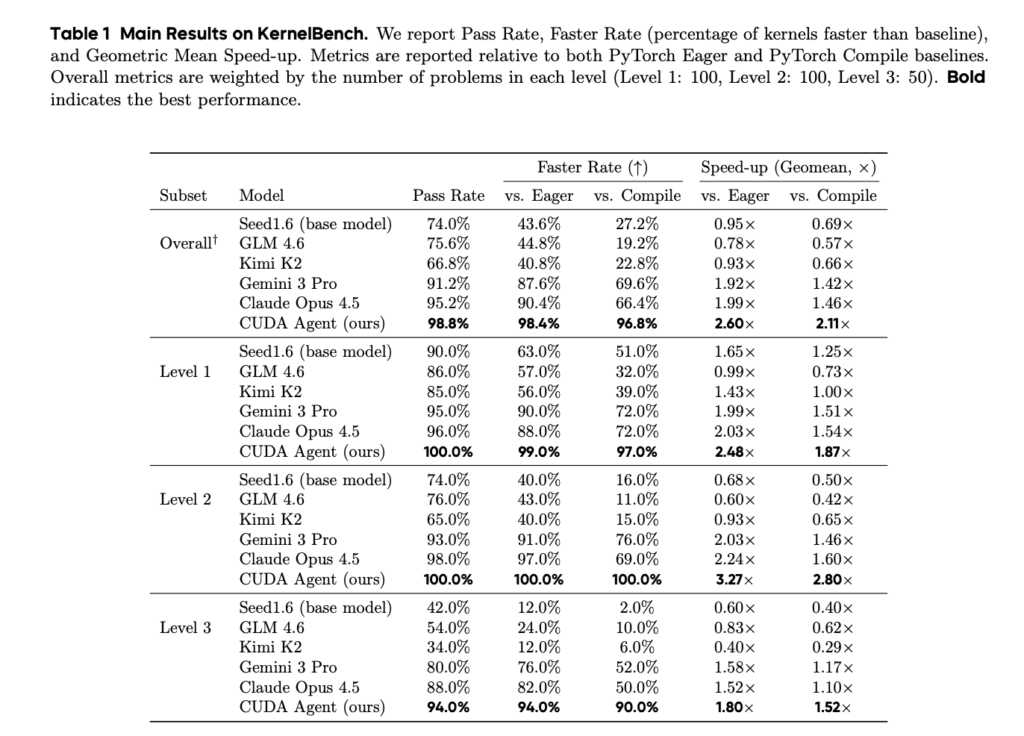
ByteDance Seed and Tsinghua AIR have released CUDA Agent, an agentic reinforcement learning system that trains a large language model to write GPU kernels that beat a compiler. The gap it targets is narrow but stubborn: frontier models already produce correct CUDA, they just produce slow CUDA. On KernelBench, the base model Seed1.6 passes 74.0%

ByteDance Seed and Tsinghua AIR Introduces CUDA Agent: A Large-Scale Agentic RL System for CUDA Kernel Generation Read More »

MiniMax Releases MiniMax-Music3: An Open-Weights Music Model Generating Complete Five-Minute Songs From Lyrics and a Structured Caption

MiniMax released MiniMax-Music3, an open-weights text-to-music model. The model takes two separate inputs: lyrics carrying section tags, and a detailed music description. It returns a complete song of up to five minutes in a single generation, as 32 kHz, 16-bit stereo WAV. The architecture pairs a Hybrid-LM, an 8B Global LLM with a 0.6B Local

MiniMax Releases MiniMax-Music3: An Open-Weights Music Model Generating Complete Five-Minute Songs From Lyrics and a Structured Caption Read More »

DeepSeek AI Releases DeepSeek Harness in Developer Preview: An MIT-Licensed Agent Harness Where Everything is a Plugin

DeepSeek released DeepSeek Harness v0.1 in developer preview and published the full source code under the MIT license. The project ships as dsh at deepseek-ai/deepseek-harness. A harness is the layer between a model and the environment it acts in — the tools, files, sandboxes, and control loop that let an agent keep working. DeepSeek frames

DeepSeek AI Releases DeepSeek Harness in Developer Preview: An MIT-Licensed Agent Harness Where Everything is a Plugin Read More »

Fine-Tuning Tool-Calling LLMs: A Complete Guide Using XYZ-Aquila-SFT and Qwen3

In this tutorial, we implement an end-to-end supervised fine-tuning pipeline for the XYZ-Aquila-SFT dataset, Hugging Face Transformers, PyTorch, and PEFT. We stream and inspect the dataset, parse multi-turn tool-use trajectories, extract structured tool calls, analyze corpus characteristics, and preserve embedded reasoning and observation patterns. We then convert tool schemas between message-embedded and structured formats, render

Fine-Tuning Tool-Calling LLMs: A Complete Guide Using XYZ-Aquila-SFT and Qwen3 Read More »

Z.ai Ships GLM-5.3 Without Retraining the Base Model: Better at Complex Coding and Long-Horizon Tasks

Z.ai just released GLM-5.3. GLM-5.3 runs on the same 743B base model as GLM-5.2. Every reported gain comes from scaled post-training: more task environments, more environment types, longer training. The results land in two places. Coding jumps most on the longest-horizon benchmarks, with Terminal-Bench 3.0 moving from 4.6 to 28.3. Cybersecurity moved further than Z.ai

Z.ai Ships GLM-5.3 Without Retraining the Base Model: Better at Complex Coding and Long-Horizon Tasks Read More »

Meet Needle 2: An Open 45M-Parameter Tool-Calling Model That Ships as a 14MB Binary and Runs a Full Session in 28MB of RAM

Cactus Compute has released Needle 2, an open 45M-parameter model for tool calling, device use, and structured extraction. The entire model ships as a single 14MB binary that runs a full session in about 28MB of RAM. Weights are trained and deployed at CQ2-bit using Cactus Quants, and the model is sealed inside the company’s

Meet Needle 2: An Open 45M-Parameter Tool-Calling Model That Ships as a 14MB Binary and Runs a Full Session in 28MB of RAM Read More »

Create a Reasoning-Focused LLM: A Practical Guide to Streaming, Curating, and Fine-Tuning the SupraLabs Reasoning Corpus

In this tutorial, we build an end-to-end workflow for working with the SupraLabs reasoning corpus. We stream a representative subset directly from the Hugging Face Hub, inspect its source distribution, token-length patterns, task composition, and reasoning-to-answer ratios, and then apply a series of quality filters to remove unsuitable training examples. We transform the retained samples

Create a Reasoning-Focused LLM: A Practical Guide to Streaming, Curating, and Fine-Tuning the SupraLabs Reasoning Corpus Read More »

Google AI Just Released Gemini 3.7 Flash: A Coding and Agent Model at $0.75/1M Input Tokens

Google has released Gemini 3.7 Flash, the newest model in its Flash tier, three weeks after Gemini 3.6 Flash. The model card describes it as a refinement of 3.6 Flash with algorithmic improvements to the core reasoning foundation — not a new pretraining run. It accepts text, images, audio, and video across a 1M-token context

Google AI Just Released Gemini 3.7 Flash: A Coding and Agent Model at $0.75/1M Input Tokens Read More »

Liquid AI Releases LFM2.5-VL-3B: A 3B Vision-Language Model That Reads Screens, Grounds Objects, and Calls Tools On-Device

Yesterday, Liquid AI released LFM2.5-VL-3B. It is a 3.1B-parameter vision-language model built for on-device deployment. The model reads digital screens across mobile, web, and desktop. It grounds objects to coordinates, parses documents and charts, and calls tools from text or image input. Liquid AI reports an average of 69.4 across 28 vision benchmarks. That matches

Liquid AI Releases LFM2.5-VL-3B: A 3B Vision-Language Model That Reads Screens, Grounds Objects, and Calls Tools On-Device Read More »