agentic ai

Auto Added by WPeMatico

ByteDance Seed Introduces SeedRealtime: a Native Audio-Visual Full-Duplex LLM That Watches, Listens and Speaks in One Model

ByteDance’s Seed team has introduced SeedRealtime, a native audio-visual full-duplex LLM. The model fuses audio, video and text in a single unified architecture. It interacts in real time over continuous multimodal streams, rather than one turn at a time. Seed positions it as a step toward omni-modal interaction, and claims three breakthroughs: joint audio-visual understanding,
ByteDance Seed Introduces SeedRealtime: a Native Audio-Visual Full-Duplex LLM That Watches, Listens and Speaks in One Model Read More »

NVIDIA Releases NemotronLabs VoiceChat 11B: An Open Full-Duplex Speech-to-Speech Model with ~450 ms Turn-Taking and Live Tool Calling

NVIDIA has released NemotronLabs VoiceChat 11B, an open 11B end-to-end speech-to-speech model for real-time, full-duplex conversation. Instead of chaining ASR, an LLM, and TTS, it performs streaming speech understanding and speech generation in one unified network. That removes the multi-model orchestration and API handoffs a cascaded stack requires, and cuts end-to-end latency: measured smooth turn-taking

NVIDIA Releases NemotronLabs VoiceChat 11B: An Open Full-Duplex Speech-to-Speech Model with ~450 ms Turn-Taking and Live Tool Calling Read More »

Top LLM Observability and Evaluation Platforms in 2026: Langfuse, LangSmith, Braintrust, Arize, and More Compared

LLM applications fail in ways traditional software does not. The same prompt can produce different outputs. A retrieval step can return the wrong document while every HTTP status reads 200. An agent can loop through fourteen tool calls, burn thousands of tokens, and deliver a confidently wrong answer. Standard application performance monitoring (APM) alone does

Top LLM Observability and Evaluation Platforms in 2026: Langfuse, LangSmith, Braintrust, Arize, and More Compared Read More »

Meet Shepherd: An Open-Source Python Substrate That Lets Meta-Agents Fork, Replay, and Revert Any Agent Run

Long-running agents accumulate state that no transcript captures. A coding agent at step 10 holds edited files, a running dev server, installed packages, and a warm prompt cache. When it misreads a traceback and rewrites a file that was already correct, neither available recovery path is cheap: patching forward grows the context and the token

Meet Shepherd: An Open-Source Python Substrate That Lets Meta-Agents Fork, Replay, and Revert Any Agent Run Read More »

Pokee AI Releases Pokee-Isaac 28B: A 10M-Token Context Agentic Model Built to Run Inside the Customer Boundary

Long-horizon agents accumulate context faster than they resolve tasks. Every tool output, observation, and intermediate reasoning step stays in the window, and the two capabilities that matter — holding that context and staying coherent across it — have so far been available almost exclusively from cloud endpoints. That excludes regulated industries, public-sector institutions, and on-device

Pokee AI Releases Pokee-Isaac 28B: A 10M-Token Context Agentic Model Built to Run Inside the Customer Boundary Read More »

Seedance 2.5 video creation

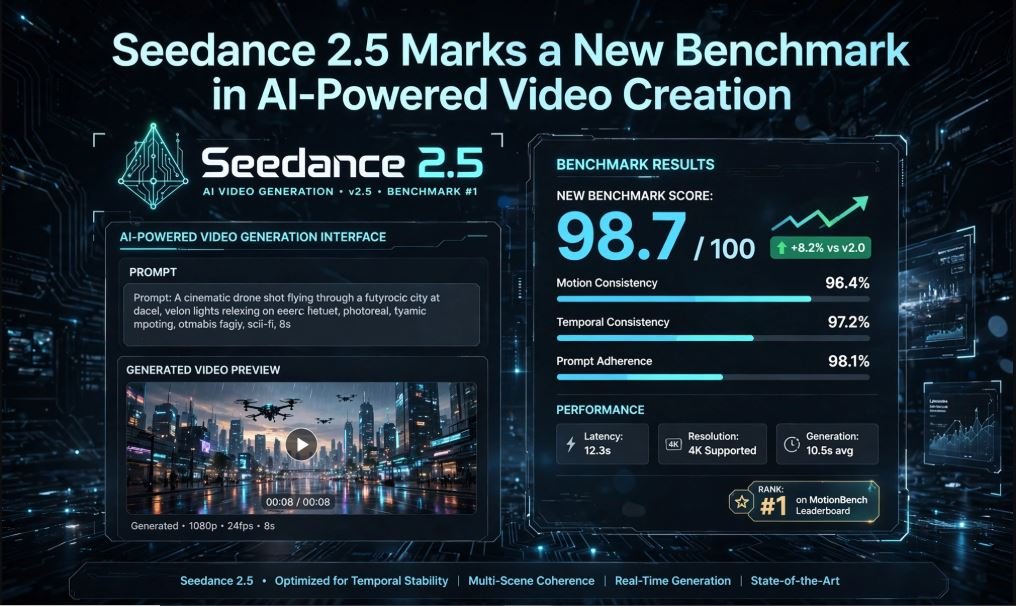
Seedance 2.5 Marks a New Benchmark in AI-Powered Video Creation

ByteDance’s generative video platform raises the bar for cinematic control, motion realism, and production-scale output — drawing attention from creators and studios alike The landscape of AI video generation has shifted considerably in the past 18 months, but few tools have drawn as much industry attention as Seedance 2.5, ByteDance’s latest iteration of its generative

Seedance 2.5 Marks a New Benchmark in AI-Powered Video Creation Read More »

Mistral AI Releases Shieldstral 1.0 3B: An Open-Weights Policy-Adaptive Multimodal Safety Classifier Matching Models 7× Its Size

Mistral AI has released Shieldstral 1.0 3B, an open-weights, policy-adaptive multimodal safety classifier that treats content moderation as a single yes/no question rather than a fixed taxonomy of harm categories. Most guardrail models bake their category list into the weights, so re-targeting one to a new deployment context means retraining — and the same content

Mistral AI Releases Shieldstral 1.0 3B: An Open-Weights Policy-Adaptive Multimodal Safety Classifier Matching Models 7× Its Size Read More »

Tencent Cloud Open-Sources TencentDB Agent Memory v2.0: A Team-Level Memory Hub for AI Coding Agents

Tencent Cloud has open-sourced TencentDB Agent Memory v2.0, a team-level memory hub for AI agents. The idea is super simple: if project context was already explained once, a new session should not need it repeated. The system turns conversations, documents and code into four reusable memory assets — Chat Memory, Skill, LLM-Wiki and Code-Graph —

Tencent Cloud Open-Sources TencentDB Agent Memory v2.0: A Team-Level Memory Hub for AI Coding Agents Read More »

NVIDIA AI Releases NOOA: An Object-Oriented Python Framework That Turns an AI Agent Into a Single Python Class

NVIDIA Labs has open-sourced NOOA (NVIDIA Object-Oriented Agents), a model-agnostic Python framework for building AI agents. Agent development today is split across prompt templates, tool schemas, callback code, and workflow graphs. NOOA collapses all of it into one Python class. Methods are the actions the model can take. Fields are agent state. Docstrings are prompts.

NVIDIA AI Releases NOOA: An Object-Oriented Python Framework That Turns an AI Agent Into a Single Python Class Read More »

Microsoft Open Sources code-testing-generator: a Polyglot Unit-Test Agent That Hits 92.1% Task Completion Versus 78.9% for Stock Copilot

Microsoft has open sourced code-testing-generator, a polyglot agent that writes unit tests and then proves they work. It ships in the dotnet-test plugin inside the MIT-licensed dotnet/skills repository. The agent targets a gap that coding assistants usually leave open. A prompt like ‘generate unit tests’ does not say which framework, file location or assertions to

Microsoft Open Sources code-testing-generator: a Polyglot Unit-Test Agent That Hits 92.1% Task Completion Versus 78.9% for Stock Copilot Read More »